Signal
Loading the stream…
Loading the stream…
What’s moving in agentic workstations and workflows — drawn from a reviewed source list, scored, and kept at a permanent address you can cite.
Curated and full layers · newest first · scored, sourced, citable
The ledger as a map. Dashed edges are machine-suggested (embedding similarity and duplicate clusters); solid edges are editorial — they appear only where a blog post cites an entry.
Raw data: signal-graph.json
Filter by category
518 entries in the full stream matching the current filters
EREBOTS 4.0 is an open-source hybrid multi-agent framework for conversational assistants. Language-model agents plan and route work, deterministic MCP tools compute exact results, and specialist agents communicate through A2A. The framework adds agents by URL configuration and manages identity, consented user context, task states, and traces. Its A2A server passed 97 official compatibility-kit requirements.
Provides a concrete reference architecture for teams combining language-model routing, deterministic tools, and interoperable specialist agents while preserving task state and traces.
A study mechanically rechecks 10 code-fix claims made by a coordination agent in a live multi-agent platform. Among claims detailed enough for deterministic re-verification, half fail the claimed identifier or call-site check, showing that some PASS declarations do not establish completed fixes.
Provides a concrete verification protocol and measured failure data for teams accepting agent-reported repairs. The small, platform-specific sample limits broad generalization.

Anthropic engineers Katelyn Lesse and Angela Jiang describe the Claude Platform’s architecture, including Opus 5.5 deployment, separation of model reasoning from tool execution, API scaling, and reliability measures for managed agents.
For agent builders, the architecture discussion provides a concrete reference for dividing reasoning, orchestration, tool execution, and operational reliability.
A local browser implementation uses LFM3-VL-2B with WebGPU to generate real-time captions for video.
Shows a concrete browser-based vision-language setup that readers can adapt for local, private multimodal inference.

The article examines the emerging AI SRE role, including how AI agents could handle on-call work, whether they can operate reliably while engineers sleep, and where vendor demonstrations differ from production practice.
It tests an agent role against incident-response realities, where reliability, escalation, ownership, and safe handoffs determine whether automation is usable.

A guide to configuring an offline coding agent with OpenCode, Ollama, and the Qwen model, including instructions for setup and use without a cloud connection.
Provides a concrete local-agent configuration for readers who need privacy, lower latency, or operation without reliable internet access.
A custom CUDA inference engine reportedly runs four coding agents concurrently on one RTX 3090 with Qwen3.8-27B, delivering about 290 tokens per second in total and three to four times llama-server’s parallel throughput.
A specific local-inference setup with concurrent-agent throughput and a comparison baseline, useful for estimating GPU capacity and agent concurrency.

The creator demonstrates running a 27-billion-parameter language model on a Khadas Mind Pro mini PC with a dock, while noting that his initial troubleshooting focused on the wrong problem.
A compact local-AI hardware test provides a concrete example of what a palm-sized workstation can handle.
FlashScript compiles successful agent runs into reusable neuro-symbolic programs, turning actions and transformations into code, parameterizing instance-specific values, and retaining LLM calls only where judgment is needed. Tests on 120 analytics tasks reported deterministic tool calls, 70-fold lower input-token use, one-third runtime, and correct generalization to 108 unseen instances.
Provides a concrete compilation model and measured results for turning recurring agent behavior into testable, maintainable software assets.
OpenAI highlights Greptile’s use of GPT-6 Astra to test user workflows, Daybreak to strengthen security, and Codex to reduce rework.
Provides a concrete software-team deployment pattern combining workflow testing, security review, and code rework reduction.
A technical discussion of unlocking FP32 accumulation on NVIDIA GPUs, comparing support across Turing, Ampere, and Ada with consumer Blackwell while addressing common misconceptions.
Records a version-specific hardware capability and architectural limits useful for validating GPU configurations and troubleshooting unsupported acceleration paths.

Notebookcheck says HP OmniBook Ultra 16 Spark delivers strong performance per watt and a well-designed chassis, but its $3,200 32 GB configuration is costly and bundled software still needs refinement. Buyers are advised to select RAM options carefully.
The review exposes memory-pricing and software caveats omitted by headline specifications, giving prospective buyers concrete comparison points before purchasing.

Alex Ziskind demonstrates a 27-billion-parameter language model running on the Khadas Mind Pro and discusses troubleshooting a mistaken fix while using the compact computer.
Useful first-hand evidence for assessing local-model performance, configuration, and troubleshooting before investing in compact inference hardware.
OpenAI presents Signals data covering 165 work activities across nearly 100 countries, showing how people use ChatGPT for work and how usage changes over time.
Large-scale proprietary usage data can ground assessments of where AI assistance is entering real work, though the release does not provide step-by-step methods.
A LocalLLaMA user reports that their RTX 3090 has failed and asks for recommendations on a replacement graphics card.
May document a hardware failure and provide current replacement options, though the missing excerpt limits assessment of technical detail.
OpenAI describes its engineers’ use of Codex Ultrafast for incident investigation, security analysis, code refactoring, and daily coding workflows, reporting investigation times reduced from hours to minutes.
A first-party account of applying an AI coding agent to incident response, with concrete use cases but limited methodological detail.
A Digital Spaceport video claims that unlocking an Nvidia RTX 3090 can accelerate local-AI prefill by 62%. The supplied description contains only standard YouTube promotional text, with no setup instructions, benchmark method, or supporting details.
The claimed 3090 prefill improvement may interest local-AI builders, but the provided material lacks configuration steps or evidence needed to evaluate it.

LangChain describes a shared internal company harness built around five components, using agents for go-to-market and engineering tasks such as monitoring leads, answering account questions, drafting pull requests, and reviewing code.
Firsthand account of deploying agents across several teams, including reusable primitives and coordination problems encountered in multi-agent use.
An RTX 3080 20GB installation reportedly gained Resizable BAR and peer-to-peer access, increasing prompt-processing throughput by 70%.
A specific local-inference configuration change with a substantial measured gain, useful for readers operating comparable GPU setups.

Workmux presents a tmux-based workflow for running multiple coding agents in parallel, with the project linked from its own site and discussed on Hacker News.
A concrete terminal multiplexing setup addresses coordination of parallel coding-agent sessions, a recurring workflow problem.
A LocalLLaMA post titled “Backup your quants!” urges users to preserve quantized local-language-model files; no further details are available from the title alone.
The post identifies a concrete maintenance step for local-model users, but the title provides little information about the cause, scope, or method.
The project introduces Architectural Deliberation Records for AI-assisted development, stored in Git. Its ORRCF prompt format asks models to present options, recommendations, rationale, confidence, and falsifiers for human approval, while generated ADRs preserve design choices and the conditions that would alter them.
It offers a concrete, Git-native method for retaining model decisions and making human oversight reviewable; the author reports using it across projects for more than a year.
The title claims that 32 GB M6 Mac Mini systems can run the Qwen3.8-27B model at high quality using the Apple Neural Engine.
It identifies a hardware-specific local inference setup that owners of this Mac Mini configuration could test and reproduce.
The post warns that streaming n-grams from an SSD during local LLM use can increase SSD wear.
It identifies a storage-health consequence local inference users may overlook and gives them a reason to inspect SSD-intensive model workflows.

LangChain explains how agent harnesses can retrieve task-relevant information efficiently, avoiding oversized results, stale data, and wasted context. It frames these techniques through the design of its Deep Agents harness.
Provides a first-party account of retrieval design choices within a working agent harness, useful when selecting search, filtering, and context-loading strategies.
UX practitioners report that AI saves time across most tasks, but unreliable outputs, organizational mandates, and inflated expectations offset many efficiency gains, leaving many practitioners ambivalent about using it.
Useful for assessing AI adoption beyond productivity claims, especially the organizational and reliability conditions that determine whether time savings translate into better work.

Alex Ziskind compares an MSI RTX Spark laptop with an NVIDIA DGX Spark and examines performance after disconnecting the desktop from power.
A firsthand comparison of current local-AI hardware includes an unusual unplugged test that may clarify performance and power constraints.
A post detailing which software or firmware unlocks exist for RTX consumer GPUs, which specific GPU models are affected, which AI/ML tasks benefit, and which unlocks are practically feasible to perform.
Maps specific RTX consumer GPU unlocks to concrete AI workloads, letting readers judge which modifications are worth attempting on their own hardware.
A Reddit post on r/LocalLLaMA asking about the likelihood of backdoors in popular LLM harnesses and inference engines.
Raises supply-chain security questions for open-source LLM tooling, but the post is a question with no excerpt, offering no concrete findings.
A Show HN project used AI to turn 45,000 Enron emails into a wiki, with factual statements linked back to source messages.
It provides a concrete example of large-scale document synthesis with traceable citations, useful for evaluating similar research or archive workflows.
A Show HN submission presenting typeui.sh/micro-interactions, a curated library of prompts for generating UI micro-interactions (hover effects, transitions, feedback states) with AI coding assistants.
Concrete prompt pack for AI-assisted UI motion work. Worth a look for designers and front-end developers needing starting points for micro-interactions.

A Level1Techs video presents a workstation build aimed at reducing AI inference costs, pairing an AMD EPYC 9575F processor with a Silverstone Alta T2 case for business-level local AI workloads.
Hands-on build from a trusted reviewer targeting cheaper local LLM inference, useful for anyone weighing self-hosted AI against API pricing.

Anekha Sokhal from Moshi describes how the tool converts market data into actionable insights for traders and argues AI tools must conform to existing trader workflows rather than disrupt them.
Highlights a concrete design principle — AI tools succeed by fitting established workflows, not replacing them — through a specific trading use case.
A pull request to llama.cpp details a method for surpassing existing decode performance benchmarks on an AMD R9700 GPU, likely accompanied by test results in the PR.
Concrete PR-level guidance for AMD R9700 owners running local inference; narrower and more specific than typical LocalLLaMA threads.
A blog post detailing how to replicate the Omarchy Linux Hyprland tiling-window-manager workflow on macOS, covering configuration and keybinding translation between platforms.
Useful reference for macOS users who want DHH's Omarchy tiling setup without leaving macOS, though it covers a niche niche with limited primary documentation.
A speculative decoding scheme for large language models that exceed available GPU memory: a 2-bit quantized copy of the model lives in VRAM while the exact residual weights stay in system RAM and serve as a verifier during draft-and-validate decoding.
Concrete VRAM/RAM split that may let users run models larger than their GPU, with exact weights retained as a check rather than discarded.
Kitten-TTS 2 is an open-source text-to-speech model using 1.58-bit quantization, running on CPU only, with voice cloning, multilingual support, and emotion control capabilities.
A CPU-only, ultra-low-bit TTS with cloning and emotion control is a rare combination worth tracking for local agent and accessibility builds.
Source page contains only YouTube's default boilerplate text; no actual transcript, description, or substantive content from the video is available. The title suggests a personal take on AI's effect on focus.
No usable content beyond a generic YouTube placeholder. Title hints at focus tips but nothing to evaluate.
A claimed free optimization hack for the RTX 3090 GPU reportedly yields 15% faster prompt processing and 5% faster token generation in local LLM inference, with stated verification.
Specific benchmarked speedups on a common consumer GPU are worth a look for anyone tuning local inference throughput.
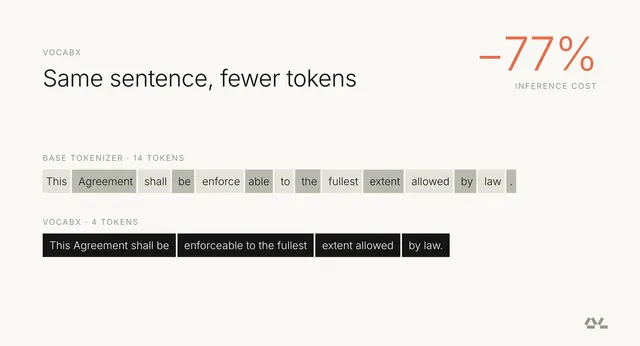
Dharma-AI specialized the vocabulary of Qwen3-4B for a production Portuguese essay grading system, replacing the general-purpose Qwen tokenizer. By designing vocabulary around per-token cost rather than token frequency, they reduced measured inference cost by 77% without retraining the base model. Results preview a forthcoming VocabX paper.
Production case where tokenizer redesign, not model retraining, delivered the largest cost reduction. Concrete frame for anyone deploying narrow-domain models while inheriting the base tokenizer.
Podcast interview with Tenex founders Alex Lieberman and CJ Hess on building an AI-native software development lifecycle for Fortune 2000 enterprises, covering outcomes-based pricing, agent-driven development, and the practical challenges of enterprise AI adoption at scale.
Founders describe their actual enterprise AI delivery model and SDLC structure — concrete patterns for teams moving from AI demos to production work in large organizations.
Researchers identify a micro-wait problem in agentic systems: runs last minutes, too long to watch yet too short to leave. They introduce Sidecar, a parallel assistant that reads the agent's run and surfaces implicit decisions, tested in a within-subjects study with 16 users.
Names a specific UX gap in long-running agents and offers a tested design pattern. Directly applicable to anyone building or choosing agent interfaces.
Sourcegraph blog noting two critical unauthenticated RCE bugs patched in PHP, promoting their Deep Search to locate PHP runtimes and Agentic Batch Changes to apply fixes across a codebase.
Vendor-flavored example of combining code search and agent-driven batch edits, but the post is a product plug rather than a reusable guide.

Analysis of data from 27 companies examining whether increased AI tool spending by software engineers has actually affected shipping velocity and pull request output.
Multi-company empirical data on whether AI tool spending translates to measurable engineering output, useful for budgeting and adoption decisions.

Open-source OSINT tool called VoidAccess that automates dark web data collection, filters noise and NSFW content, and presents results as a graph. Installed and run via a few CLI commands, with configurable time limits.
Single-creator Show HN for a niche security tool; description is self-promotional, offers no benchmarks or comparison to existing OSINT pipelines, and sits outside the agentic-workstation scope.
A technique for improving low-bit quantization quality of Qwen3-8B by using a prefiller model streamed from SSD during inference, potentially mitigating quality loss in aggressive quantization.
Concrete inference setup for local LLM users running heavily quantized models. Worth a look if you hit quality issues at low quants.
An independent Schlotzsky's and Cinnabon franchisee reduced menu repricing time by 95% using ChatGPT Work, with potential to free up $100K in cash flow.
Concrete outcome figures from a real operator, but the post lacks the workflow steps needed to replicate it.

A practitioner's comparison of six decision models (Jev, Perplexity Decider, Liquid d1/d1-ultra, Cloudflare Clef, OpenAI Decisions) for automated agent evals, covering threshold tuning, cost vs performance tradeoffs, calibration, and confidence score interpretation using 100 apartment leasing agent traces.
Firsthand benchmark across six decision model providers with threshold tuning and calibration guidance — directly actionable for teams building eval pipelines for agents.
A post asserting that 24GB of VRAM is sufficient for running multiple local AI engines sequentially, loading them one at a time rather than concurrently, to fit within consumer GPU memory limits.
Directly addresses a common VRAM constraint for local LLM practitioners with a sequential-loading strategy worth weighing against parallel setups.
A Reddit user on r/LocalLLaMA warns others not to upgrade the Strata software, claiming it contains numerous breaking changes.
A heads-up for current Strata users, though no details on the nature of the breakage or alternatives are provided.