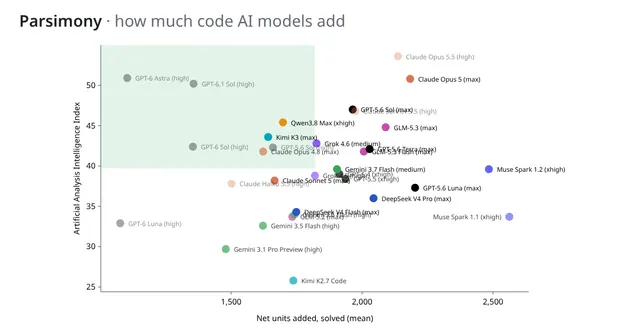
Show HN: Parsimony – an open-source benchmark for how much code AI models add
2.85T2 sourceHacker News · Show HN (50+ points)
Source record
Published by Hacker News · Show HN (50+ points) (T2 source). The original is at https://parsimony.lasu.dev/.
Pipeline notes
The summary and note below are generated by the signal pipeline — they are Beyond Desk’s reading, not quotations from the source.
SummaryParsimony is an open-source benchmark that measures net code volume added by AI models on tasks from SWE-bench Verified, SWE-bench Live, and DeepSWE. It counts syntax units (statements, calls, names, literals) rather than lines, and subtracts deleted code. The author ran newer models (GPT-6, Claude 5.5) manually on 3–10 tasks since public patches are unavailable.
Why it mattersFirsthand tool addressing a gap: existing coding benchmarks reward solve rate but ignore codebase bloat, which shapes long-term maintainability. Open to community contributions.
Cited by
No citations on record.