How Specializing the Vocabulary of SLMs Can Cut Inference Cost by 77% in Real Applications
3.60T1.5 sourceHugging Face Blog
Source record
Published by Hugging Face Blog (T1.5 source). The original is at https://huggingface.co/blog/Dharma-AI/vocabx-vocabulary-specialization.
Pipeline notes
The summary and note below are generated by the signal pipeline — they are Beyond Desk’s reading, not quotations from the source.
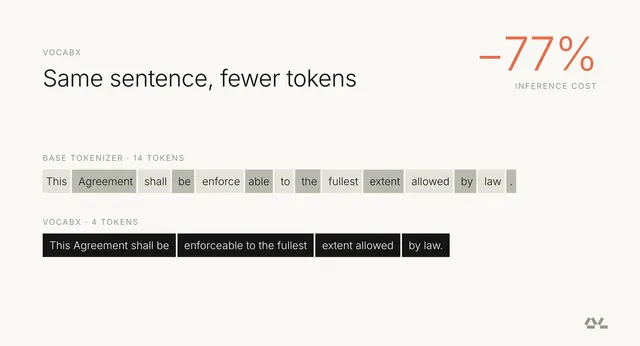
SummaryDharma-AI specialized the vocabulary of Qwen3-4B for a production Portuguese essay grading system, replacing the general-purpose Qwen tokenizer. By designing vocabulary around per-token cost rather than token frequency, they reduced measured inference cost by 77% without retraining the base model. Results preview a forthcoming VocabX paper.
Why it mattersProduction case where tokenizer redesign, not model retraining, delivered the largest cost reduction. Concrete frame for anyone deploying narrow-domain models while inheriting the base tokenizer.
Cited by
No citations on record.