Signal
Loading the stream…
Loading the stream…
What’s moving in agentic workstations and workflows — drawn from a reviewed source list, scored, and kept at a permanent address you can cite.
Curated and full layers · newest first · scored, sourced, citable
The ledger as a map. Dashed edges are machine-suggested (embedding similarity and duplicate clusters); solid edges are editorial — they appear only where a blog post cites an entry.
Raw data: signal-graph.json
Filter by category
2148 entries in the full stream matching the current filters
The paper studies pull-based messaging for large groups of language-model agents, with messages held in an inbox until recipients choose what to read and retain. Simulations of up to 16,000 agents find push messaging loses important replies under heavy traffic, while inbox rules improve request discovery; network results show partial adoption provides limited recovery.
Quantified results identify context loss and partial-adoption failures that inbox protocols can address, while the four-policy framework gives implementers a concrete structure for testing coordination rules.
EREBOTS 4.0 is an open-source hybrid multi-agent framework for conversational assistants. Language-model agents plan and route work, deterministic MCP tools compute exact results, and specialist agents communicate through A2A. The framework adds agents by URL configuration and manages identity, consented user context, task states, and traces. Its A2A server passed 97 official compatibility-kit requirements.
Provides a concrete reference architecture for teams combining language-model routing, deterministic tools, and interoperable specialist agents while preserving task state and traces.
EMMA represents a multi-agent configuration—routing memory, specialist prompts, and procedural skills—as structured episodic memory. A reflector assigns diagnosed failures to update owners, while backbone-independent guards constrain accepted edits. Across three benchmarks, five backbones, and four baselines, the paper reports top overall results and fewer training executions.
The update-ownership and admissibility rules address a recurring problem in agent evolution: changes that drift toward backbone preferences rather than observed failures.
AgentBaton studies handoffs between capable, costly models and efficient, lower-cost models during long-horizon agent tasks. Across 11 model pairs and two benchmarks, a detector trained on recurring task-progress patterns selects handoff points, cutting API costs by 65.9% on average while largely preserving accuracy and sometimes improving it.
Provides comparative evidence on handoff direction and context transfer, plus a lightweight timing mechanism applicable to multi-model agent pipelines.
A study mechanically rechecks 10 code-fix claims made by a coordination agent in a live multi-agent platform. Among claims detailed enough for deterministic re-verification, half fail the claimed identifier or call-site check, showing that some PASS declarations do not establish completed fixes.
Provides a concrete verification protocol and measured failure data for teams accepting agent-reported repairs. The small, platform-specific sample limits broad generalization.
SCOPE is a multi-agent system that profiles news outlets for bias, factuality, and credibility. It divides work among agents for article retrieval, content analysis, external evidence search, scoring, and reporting, with inspectable intermediate outputs. The preprint reports benchmark results on 200 outlets and links code and a demo.
The paper provides a concrete decomposition, benchmark, code, and inspectable interface useful for designing evidence-grounded agents whose intermediate claims and tool calls can be reviewed.

GitHub Copilot's SDK now supports server-to-server authentication for GitHub Apps installed on organizations. The public preview lets services and agents use installation credentials for requests without interactive user sign-in.
Removes an authentication obstacle for production agent deployments and provides a concrete path to organization-level service credentials.

Anthropic engineers Katelyn Lesse and Angela Jiang discuss Opus 5.5, the Claude Platform, and the internal design choices used to build AI agents.
Offers a first-hand engineering account of separating model reasoning from execution, useful when designing agent systems and tool architectures.

Anthropic engineers Katelyn Lesse and Angela Jiang describe the Claude Platform’s architecture, including Opus 5.5 deployment, separation of model reasoning from tool execution, API scaling, and reliability measures for managed agents.
For agent builders, the architecture discussion provides a concrete reference for dividing reasoning, orchestration, tool execution, and operational reliability.
A local browser implementation uses LFM3-VL-2B with WebGPU to generate real-time captions for video.
Shows a concrete browser-based vision-language setup that readers can adapt for local, private multimodal inference.

LangChain details how its GTM Engineering and design teams taught an in-house Slack design agent to produce code-based videos, graphics, UI images, and decks while incorporating company-specific design principles through four months of critique and iteration.
A first-party account of encoding organizational taste into an agent through repeated review, with implementation details on the harness and cross-functional development process.

The article examines the emerging AI SRE role, including how AI agents could handle on-call work, whether they can operate reliably while engineers sleep, and where vendor demonstrations differ from production practice.
It tests an agent role against incident-response realities, where reliability, escalation, ownership, and safe handoffs determine whether automation is usable.

Ai2 releases a study of how reliably LLMs can judge scientific idea novelty, alongside a benchmark, data, code, and an automated pipeline for constructing evaluation sets. It also describes several AI systems used across stages of scientific discovery.
Provides primary-study resources and a reproducible pipeline for teams evaluating whether LLM novelty judgments are dependable.

A guide to configuring an offline coding agent with OpenCode, Ollama, and the Qwen model, including instructions for setup and use without a cloud connection.
Provides a concrete local-agent configuration for readers who need privacy, lower latency, or operation without reliable internet access.
A custom CUDA inference engine reportedly runs four coding agents concurrently on one RTX 3090 with Qwen3.8-27B, delivering about 290 tokens per second in total and three to four times llama-server’s parallel throughput.
A specific local-inference setup with concurrent-agent throughput and a comparison baseline, useful for estimating GPU capacity and agent concurrency.

The creator demonstrates running a 27-billion-parameter language model on a Khadas Mind Pro mini PC with a dock, while noting that his initial troubleshooting focused on the wrong problem.
A compact local-AI hardware test provides a concrete example of what a palm-sized workstation can handle.
OpenAI and Oracle are expanding their partnership to integrate business applications and AI agents into ChatGPT and introduce new Oracle offerings.
The announcement identifies a concrete distribution path for enterprise agents but provides no implementation details, pricing, or deployment guidance.
AgentProofBench evaluates reusable verifiers for web agents by pairing tests of frozen acceptance rules with execution from identical saved openings. Across 97 tasks, 79 families, and four web services, experiments with DeepSeek Flash and Pro compare decision replay, paired rebuilds, and deployment-state panel correctness, while releasing benchmark artifacts and trajectories.
Provides a reproducible test structure for separating verifier quality from downstream execution, with released tasks, rules, states, programs, and failure-linked trajectories.
DynaFlow trains a main agent to synthesize executable, task-specific programs for coordinating fixed sub-agents sequentially or in parallel. It uses supervised fine-tuning and defect-filtered refinement, reporting improved accuracy, more verification, and better information flow across six reasoning, scientific问答, and retrieval benchmarks.
Separates orchestration learning from executor capability and provides a concrete model for designing, testing, and refining multi-agent coordination workflows.
EvolveMAS is a proposed framework for decentralized language-model agents that pairs each agent with a memory agent, supports within-episode adaptation and cross-episode knowledge reuse, and evaluates the approach on five benchmarks and six configurations without updating model parameters.
The paper specifies a reusable architecture for governing agent memory and carrying interaction lessons across episodes, with benchmark results and ablations for implementation choices.
Coral Discovery coordinates autonomous research agents by labeling attempted solutions, tracking progress across distinct directions, and allocating agents using exploration bonuses and direction-specific credit. Across nine tasks, it beat the strongest open multi-agent baseline on six, tied on one, and lost on two.
It provides a concrete credit-allocation pattern for preventing multi-agent convergence, supported by task comparisons and reported results in program search.
VibeGame is an AI-native framework for creating playable 2D games from natural-language prompts and optional reference images. It uses a schema-validated text engine and eight specialized agents that iteratively implement, review, test, and fix projects, then distill accepted work into reusable components. Experiments on GameCraft-Bench compare prompt-to-game and asset-assisted generation.
A detailed, game-development case study in agent role separation, interactive verification, and reusable project artifacts; it offers concrete patterns to compare with other coding-agent workflows.
AutoSwarm is a multi-agent framework that forms collaborations by assigning responsibility boundaries and acceptance conditions, then coordinates execution through shared state, dependencies, supervision, handoffs, and review feedback. It reports gains over single-agent and other multi-agent baselines on programming, planning, and financial-analysis tasks, with code released.
The paper specifies coordination mechanics and supplies code, giving practitioners a concrete basis for testing whether agent specialization improves task outcomes.
FlashScript compiles successful agent runs into reusable neuro-symbolic programs, turning actions and transformations into code, parameterizing instance-specific values, and retaining LLM calls only where judgment is needed. Tests on 120 analytics tasks reported deterministic tool calls, 70-fold lower input-token use, one-third runtime, and correct generalization to 108 unseen instances.
Provides a concrete compilation model and measured results for turning recurring agent behavior into testable, maintainable software assets.
A multi-agent system called the As-If Machine helps users co-write first-person counterfactual narratives about policy risks. Two pre-registered experiments found that these narratives increased psychological closeness more than expert vignettes or unrelated co-writing, with effects on policy attitudes varying by domain.
Documents a concrete human-AI role split: the system supplies situated detail while people supply perspective and emotion, supported by large pre-registered studies.
OpenAI News says Check Point uses Daybreak to speed vulnerability research, helping analysts translate vulnerability intelligence into protections for customers more quickly.
A named enterprise deployment shows a concrete security-research use case, though the brief description provides little workflow or implementation detail.

Amp now offers an Android app, available from ampcode.com/app or by scanning the QR code included in the announcement.
Extends access to the coding agent beyond desktop use, though the announcement provides little detail about mobile capabilities or limitations.
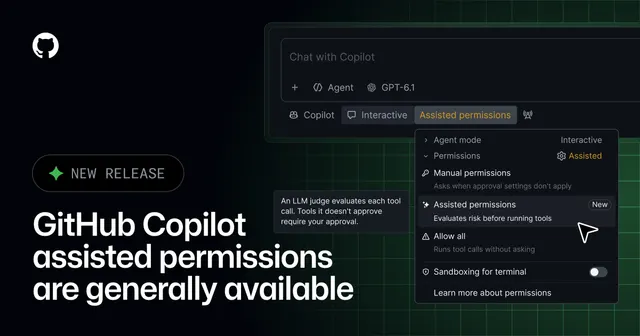
GitHub says assisted permissions are generally available in Copilot CLI, the Copilot app, and Visual Studio Code. The feature lets Copilot request permission before running commands or accessing filesystem paths.
Documents an access-control mechanism available across three agent interfaces, useful for configuring command and file permissions.
OpenAI highlights Greptile’s use of GPT-6 Astra to test user workflows, Daybreak to strengthen security, and Codex to reduce rework.
Provides a concrete software-team deployment pattern combining workflow testing, security review, and code rework reduction.
A developer reports that a custom inference engine, forked from Strata and optimized for Volta, runs Qwen-Flash-Next at nearly 400 tokens per second on three used V100 32GB GPUs in an R740 server.
Provides a concrete reference for high-throughput local inference; benchmark methodology, engine code, and reproducibility details remain unspecified.
GitHub says GPT-6.1 Terra, OpenAI's lower-cost model, is generally available in Copilot for everyday agentic coding and terminal tasks.
Documents an official model addition and its cost positioning, useful when comparing Copilot options for routine agentic work.

Supabase co-founders Paul Copplestone and Ant Wilson discuss how agent-built applications require backends that can sustain long-running workloads, coexist with databases, and expose schemas agents can understand and modify.
A founder-level discussion of backend architectural changes needed when coding agents produce and operate software, with concrete implications for database and schema design.
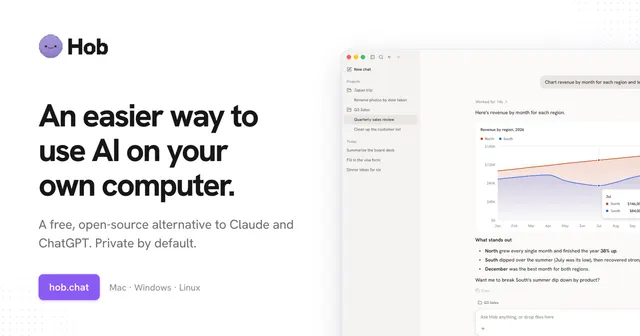
Hob is an MIT-licensed cross-platform desktop app that runs open-weight models locally and provides file access, image analysis, sandboxed Python, web search, MCP connectors, and filesystem operations without sending chats or files to a hosted service.
The creator documents hardware detection, GPU compatibility issues, and Electron integration with llama.cpp, providing useful implementation details for reproducing a local setup.
The post introduces ConvFill as a method for building faster voice agents.
The title indicates a latency-focused voice-agent approach, but the absent excerpt limits assessment of its implementation and results.

Alex Ziskind demonstrates a 27-billion-parameter language model running on the Khadas Mind Pro and discusses troubleshooting a mistaken fix while using the compact computer.
Useful first-hand evidence for assessing local-model performance, configuration, and troubleshooting before investing in compact inference hardware.
OpenAI describes CodeRabbit using GPT-6.1 Sol in a security agent that examines risks across complex codebases, presents findings and proposed fixes, and supports developer review.
It illustrates an agent-review loop for code security, separating automated investigation from human approval of proposed remediations.
OpenAI describes its engineers’ use of Codex Ultrafast for incident investigation, security analysis, code refactoring, and daily coding workflows, reporting investigation times reduced from hours to minutes.
A first-party account of applying an AI coding agent to incident response, with concrete use cases but limited methodological detail.
The paper shows how hidden instructions in tool-decoded images or metadata can enter MCP agent workflows, bypassing text scanners. It proposes decode-time provenance binding with authenticated trust labels, a provenance ledger, context-taint tracking, and tool-call blocking, evaluated on 24 adaptive payloads in a testbed.
Provides a tested MCP containment design, attack carriers, ablation results, and public code and data for teams assessing indirect prompt-injection defenses.
The paper presents a multi-agent framework for public-health surveillance that discovers and assesses sources, structures evidence, links events, and validates records. Retrospective tests recovered 13 hantavirus cases, closely reconstructed Canadian measles counts, and increased recent mpox-report coverage by incorporating attributed media.
Provides a concrete agent-task decomposition, comparative outbreak metrics, and explicit record-quality limits. Useful as a workflow design reference, though prospective timeliness gains remain untested.
UniMASO jointly optimizes role-specific prompts and model assignments in multi-agent systems using local, downstream, and global feedback. Its cost-aware Pareto search and topology-aware co-evolution reportedly preserve task performance while reducing token-weighted deployment cost across five benchmarks and execution topologies.
Provides a tested method for assigning different models to agent roles and optimizing prompts together, with reported cost reductions and public implementation code.
CRM-Agent-Bench introduces 555 stateful, multi-turn CRM tasks across nine business domains, with executable contracts checking actions, arguments, ordering, responses, target state, protected state, and policy compliance. Sixteen evaluated systems show similar strict-success rates but substantial differences in cost and domain reliability.
Provides an auditable benchmark and public task suite for testing whether agents execute consequential business workflows correctly, not merely return plausible answers.
A Reddit user asks whether reports of AI agents mass-deleting an entire drive are outdated or still occur.
The thread may collect current failure reports, but the title provides no reproduction details, safeguards, or verified incident.
A Digital Spaceport video claims that unlocking an Nvidia RTX 3090 can accelerate local-AI prefill by 62%. The supplied description contains only standard YouTube promotional text, with no setup instructions, benchmark method, or supporting details.
The claimed 3090 prefill improvement may interest local-AI builders, but the provided material lacks configuration steps or evidence needed to evaluate it.
A Reddit show-and-tell post presents PolyStrata running on a $20 Xeon server.
A low-cost, first-hand deployment may provide a useful reference for running agent software on modest local hardware.

LangChain describes a shared internal company harness built around five components, using agents for go-to-market and engineering tasks such as monitoring leads, answering account questions, drafting pull requests, and reviewing code.
Firsthand account of deploying agents across several teams, including reusable primitives and coordination problems encountered in multi-agent use.
An RTX 3080 20GB installation reportedly gained Resizable BAR and peer-to-peer access, increasing prompt-processing throughput by 70%.
A specific local-inference configuration change with a substantial measured gain, useful for readers operating comparable GPU setups.
A LocalLLaMA discussion asks whether users should switch from OpenCode to another AI coding tool, without providing details in the available excerpt.
The title identifies a tool-migration question, but the missing discussion offers no reusable comparison, setup, or supporting evidence.
The creator introduces Radian, a compact coding agent, and arc, a built-in orchestrator that delegates work to concurrent headless agents, reviews results, runs CI/CD, integrates changes, and tracks progress in a TUI. Humans approve work items and final validation.
A concrete open-source implementation of agent-to-agent delegation with approval gates, CI/CD, and progress tracking; useful as a setup reference, though adoption and independent validation remain limited.

Workmux presents a tmux-based workflow for running multiple coding agents in parallel, with the project linked from its own site and discussed on Hacker News.
A concrete terminal multiplexing setup addresses coordination of parallel coding-agent sessions, a recurring workflow problem.
A LocalLLaMA post titled “Backup your quants!” urges users to preserve quantized local-language-model files; no further details are available from the title alone.
The post identifies a concrete maintenance step for local-model users, but the title provides little information about the cause, scope, or method.