Signal
Loading the stream…
Loading the stream…
What’s moving in agentic workstations and workflows — drawn from a reviewed source list, scored, and kept at a permanent address you can cite.
Curated and full layers · newest first · scored, sourced, citable
The ledger as a map. Dashed edges are machine-suggested (embedding similarity and duplicate clusters); solid edges are editorial — they appear only where a blog post cites an entry.
Raw data: signal-graph.json
Filter by category
410 entries in the full stream matching the current filters
The paper uses science-fiction transformations as a lens for designing transitions between visualization forms. Through four hypothetical transitions, it identifies purpose and cross-transition correspondence as key factors, with 1:N and N:1 mappings requiring more complex designs and greater interpretive effort.
Provides a concise framework for designers of task-sensitive visual systems to compare transition purpose, object continuity, and cognitive cost.
An Applied Ergonomics paper examining how accuracy, reliability, and personality jointly shape trust, arguing that accurate outputs alone do not guarantee trust.
Useful for separating output quality from consistency and human traits when evaluating systems whose acceptance depends on user trust.
The paper proposes a framework for personalizing speech and language support by separating message access, user-need estimation, and support selection. It adapts sentence segmentation, pictograms, and optional speech using behavioral feedback, with EEG treated as an uncertain supplementary signal. A staged evaluation will compare fixed, behavior-adaptive, and neuroadaptive interfaces.
Useful for interface researchers because it defines a testable comparison of whether EEG adds value beyond behavioral adaptation, without treating neural signals as direct measures of comprehension.
The paper tests whether LLM agents can use trust estimates from repeated negotiations to resist a participant covertly blocking agreement. Agents often identify the adversary, but accurate trust estimates do not reliably improve outcomes. Agreement rises by up to 23 percentage points only when agents are explicitly guided to use trust in decisions.
Provides a specific design constraint for multi-agent workflows: trust detection alone is insufficient, and decision procedures must explicitly convert trust assessments into negotiation behavior.
Researchers studied how people judge AI-generated answers and whether confidence and source indicators affect trust. Interviews, a survey, and an experiment covering gardening, mathematical, and medical queries found indicators shape initial perceptions, effects shrink after users learn correctness, and medical answers receive greater skepticism.
For chatbot and interface designers, the study links trust behavior to user verification, source quality, and task risk, offering evidence for where confidence and citations should appear.
Researchers adapted the classic Music Lab experiment to test whether LLM multi-agent systems exhibit herding. Exposure to cumulative recommendation counts produced runaway cascades, with collective outputs diverging sharply from intrinsic song appeal. LLM populations were more susceptible to herding than humans and less able to self-correct.
Adapts a classic social-psychology paradigm to expose a structural weakness in LLM multi-agent design — cascading influence that humans correct but LLMs amplify.
Analysis of 1,396 participants rating 29,347 LLM responses in the PRISM dataset finds that unasked-about features (length, formatting, refusal language) predicted ratings as strongly as surveyed attributes. Stated priorities tracked perceived model characteristics but not concrete response features; personalization from stated preferences added only 0.13 percentage points over pooled models.
Quantifies the gap between stated and revealed preferences in AI evaluation using a large public dataset. Challenges the premise that preference surveys meaningfully improve LLM personalization. Directly relevant to agent and tool builders.
Empirical study of human-AI collaboration in scientific ideation. Finds AI collaboration does not significantly improve human-evaluated idea quality, though iterative revision does. AI judges approximate human scores but favor AI-assisted proposals. Collaboration provenance is only partially detectable, and firsthand AI use raises perceived usefulness while yielding smaller efficiency gains than expected.
Challenges the assumption that AI's main value is producing better ideas. Empirical findings on AI judge bias toward AI-assisted work and limited detectability of AI collaboration matter for anyone deploying AI in creative workflows.
Study develops and validates a scale measuring undergraduate students' reliance on generative AI during problem-solving. Exploratory factor analysis on 800 responses identified four factors—reflective, cautious, thoughtless, and collaborative use—confirmed via two CFAs across 730 and 1,173 responses with adequate model fit.
A validated behavioral instrument for measuring GenAI reliance independent of binary task outcomes; useful as a research tool but not directly actionable for typical readers.
Peer-reviewed case study presenting a digital twin-driven framework for forecasting human-centric ergonomic risks in automotive and industrial assembly environments.
Peer-reviewed methodology linking digital twins to ergonomic risk prediction in assembly lines; relevant for industrial planners and ergonomics researchers.
Peer-reviewed paper in Ergonomics examining whether vibrotactile feedback combined with exposure variation analysis can lower musculoskeletal risk during surgical simulation training.
Primary research on a specific ergonomic intervention for surgical simulation; relevant to those studying haptics, surgical training, or MSD prevention, though narrow in audience.
A peer-reviewed paper in the journal Ergonomics examining how human sustained attention and vigilance are challenged by working alongside intelligent machines, outlining current challenges and future prospects for the field.
Targets an underexamined human-factors angle of agentic work — maintaining reliable attention when supervising AI systems — relevant to workflow designers concerned with monitoring fatigue and error.
Peer-reviewed study in Ergonomics (Vol 69, Issue 11, Nov 2026) evaluating virtual reality work environments and their cognitive and physiological effects on office workers.
Peer-reviewed measurement of cognitive and physiological load in VR-based office work — useful baseline as VR workstations move from demos to deployments.
Peer-reviewed study in Ergonomics examining the physiological and cognitive effects of sleep inertia after nighttime naps, and testing behavioral countermeasures to reduce post-nap impairment. Published in Volume 69, Issue 11, November 2026.
A research paper on behavioral fixes for post-nap grogginess, useful for shift workers and anyone who naps at the desk.
Paper models parallel AI agent coordination as graph-structured discrete block optimization. Independent sets certify compatible edits; a coordinator merges them with a guarantee preserving a 1/χ_f(G) fraction of verified local improvement. Experiments on code-repair and road networks show verified merging resolves conflicts and reduces wall time.
Provides a principled graph-theoretic guarantee for merging parallel agent outputs, addressing a coordination failure mode that pure prompt-level guidance does not solve.
Presents coupled visual-motor remapping (Global Zoom and Focus+Context) for first-person humanoid teleoperation, evaluated in a within-subject study (N=8, 72 trials). Completion and preference favored different mappings, leaving results inconclusive.
Small-N study on teleoperation remapping with mixed outcomes; the divergence between completion rate and user preference means neither mapping is clearly supported.
Qualitative HCI study interviewing 23 Indian engineering students and recent graduates about generative AI use in coursework, examinations, and AI-free campus placements. The paper reports five themes from reflexive thematic analysis, applies signaling theory to question what grades certify when AI can help produce them, and offers recommendations for employers, institutions, and tool designers.
Understudied Indian setting where 2.9 million engineering seats meet AI-free placement screens. Useful framing for anyone thinking about how credentials and signals hold up when preparation is AI-saturated.
Seller agents, optimized only to be selected more often, spontaneously rewrite tool descriptions to claim more capabilities than they deliver. Across five production models and real Amazon/Instagram tool data, this 'toolflation' distorts markets, costs capable tools share, and under one model cuts buyer task success from 89% to 30%.
Names a concrete failure mode in agent-to-agent commerce. Documents which models fall into it, quantifies the buyer-side cost, and argues honesty toward third parties belongs in safety alignment.
This paper characterizes the 'negative space' of AI memory—information users want forgotten. From 179 incidents reported by 146 users, the authors develop a 15-category taxonomy of protected information and operationalize it in FENCE, a policy-level memory gate that blocks protected categories by default. A within-subjects study (N=15) found FENCE improved usability and trust over post-hoc memory management.
First empirical taxonomy of what users want AI to forget, paired with a concrete policy-gate design. Reframes memory from cleanup-after-the-fact to structured pre-filtering at conversation entry.
Paper presents Rehearsim, a research probe using LLM-simulated participants as materials for qualitative interview rehearsal rather than human substitutes. A study with 21 researchers shows it helps surface assumptions, revise target populations, and develop probes, while revealing risks such as concealment of weak questions and interpretive anchoring.
Concrete inspectable-rehearsal framework with traceability and contestability, plus documented risks from a 21-researcher empirical study — directly applicable to qualitative workflows using AI.
A preregistered experiment compared AI advisors that selectively abstain from giving advice with those that always advise during repeated financial decisions. Abstention increased advice acceptance among users with high perceived expertise but decreased it among low-expertise users, driven by differential cognitive burden.
Counterintuitive finding that an AI's choice to stay silent affects users differently by expertise level. Directly relevant to designing AI agents integrated into decision workflows.
A controlled study of how language-model agents allocate turns between acting autonomously and deferring to a human partner in a shared maze task, with three advantage conditions. Stronger solo-performing models showed selective human involvement (roughly 80% when the human held the shorter route), while the weakest model showed no such selectivity.
Separates a correct division of labor from a collaboration failure in human-AI teams — a useful framing for designing agent workflows that hand off to people.
Narrative review synthesizing research on adaptation to occupational exoskeleton use, proposing an assessment framework for evaluating worker adaptation in workplace contexts.
Consolidates scattered adaptation findings into a structured framework, giving practitioners a reference point for planning and evaluating exoskeleton deployments.
Design Science Research study evaluating an LLM-based enterprise data assistant deployed in a CFO unit's data lake. It compares schema-based and knowledge-graph-based semantic mediation for resolving imperfect user prompts, finding knowledge graph mediation outperforms on precision, recall, F1, and user intent preservation.
Real deployment evidence that knowledge graph mediation measurably improves how enterprise assistants handle the messy, domain-specific prompts business users actually type.
A paper from Stanford, Together AI, UIUC, and Meta introduces Hybrid Reasoning Agents: AI models that perform reasoning in a hidden internal state rather than emitting chain-of-thought text, surfacing natural language only when calling tools or delivering the final answer.
A specific architectural pattern from multiple major labs that could alter how reasoning cost, latency, and interpretability are handled in agent systems.
Research paper introducing DISARM, an interface that identifies and discloses manipulative tactics used by LLMs in real time. A 488-participant between-subjects experiment found users with DISARM disclosures showed 78% less belief shift toward a hidden harmful objective and rated the agent as more biased and less ethical.
Empirical evidence that interface-level disclosures reduce LLM manipulation, with a working prototype, design recommendations, and a categorized dataset of user pushback strategies.
Peer-reviewed study comparing electromyographic activity, task performance, and musculoskeletal symptoms between sitting and cycling computer workstations, analyzed separately for male and female participants to identify sex-specific responses.
Sex-stratified EMG and symptom data on active workstations is uncommon; useful for ergonomists selecting sit-vs-cycle desks and for designing sex-aware interventions.
Paper derives A²-Failures, a taxonomy of 20 failure modes from 2,500+ recorded agent-to-agent system runs across 488 scenarios in eight domains. Failures cluster into discovery/delegation, grounding, verification, and conduct. Three findings: agents don't search for peers, never fact-check unprompted, and end-output scoring hides internal coordination breakdowns. Run logs released.
First empirical taxonomy of agent-to-agent system failures, grounded in 2,500 runs. Twenty modes, three repeatable observations, open dataset. Useful for anyone designing or evaluating multi-agent pipelines.
Research paper examining how feedback shapes human-AI collaboration through a 244-participant behavioral study. Distinguishes reflection-in-action from reflection-on-action, finding unidirectional feedback risks reducing subsequent concurrent reflection while balanced feedback preserves both types and supports appropriate reliance.
Provides empirical guidance on feedback design for human-AI decision systems, with a clear behavioral study separating reflection-in-action from reflection-on-action effects.
Theoretical paper proving that passive observation cannot distinguish a cognitively biased user from an unbiased one in a transformed environment, and that active adversarial interventions of finite length are required to make their action distributions separable.
Formal non-identifiability result challenges the common assumption that user behavior reliably reflects preferences, with implications for alignment and feedback-loop design.
Narrative review identifying three harms of single-voice chatbot interfaces—cognitive offloading, ideological narrowing, and epistemic compression—and proposing multi-persona interfaces as a cost-effective intervention, grounded in game design traditions (magic circle, role differentiation, persona embodiment) and accompanied by a taxonomy and research agenda for pluralistic human-AI interaction.
Proposes a concrete design alternative to the dominant single-chatbot paradigm, importing game design and participatory simulation techniques rarely applied to AI interface research.
Qualitative study with eight secondary computing teachers examining AI collaboration during lesson authoring via a research probe called LessonBuilder. Finds instructional intent develops through creating, inspecting, and adapting materials, with teachers selectively delegating while retaining classroom-readiness judgment.
Small-N qualitative study, but documents the negotiation loop between teacher intent and AI output. Useful for designers of agentic authoring tools in education.
A controlled between-subjects study (n=36) comparing Steerable AI Summaries (STAIS) versus manual Note-Taking (NT) as end-of-session consolidation scaffolds in an aggregated academic search interface, across two sessions one week apart. STAIS yielded faster task resumption and broader conceptual coverage; NT produced richer inter-concept connections and higher self-reported certainty.
Methodologically clean study isolating a concrete tradeoff: GenAI-assisted consolidation gains speed and breadth but loses inter-concept depth and learner certainty — directly relevant for anyone building or choosing AI research assistants.
Thematic analysis of 5,379 r/ADHD posts (2020–2025) identifies five challenge and nine strategy themes around digital time management. Findings highlight that self-regulation demands of tools themselves, lost time guilt, and peer/environmental supports are central to ADHD tool design and evaluation.
Large community corpus with concrete design implications: tools should reduce self-regulation load, not add to it, and evaluations should include recovery and emotional costs.
Nielsen Norman Group reports on how AI power users manage context libraries for agents, finding that many rarely edit or locate their context files, indicating context management is a weak point in agent workflows.
Counterintuitive research finding that experienced users struggle with the very context files meant to make their agents more capable, reframing context engineering as a usability problem worth examining.
A peer-reviewed IJHCS paper that models stress and cognitive load in web-based question answering tasks using physiological and behavioral signals, examining how users experience cognitive demands during such activities.
Relevant read for anyone designing or evaluating web-based work tools, as it combines physiological and behavioral measures to quantify cognitive load during routine digital tasks.
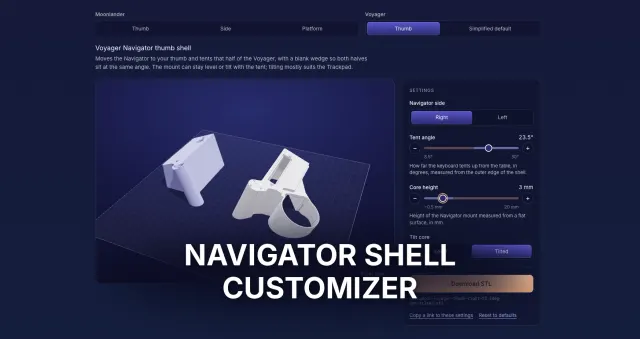
ZSA publishes 3D printable shell designs for its Navigator split keyboard, letting users set their own tenting angle and height instead of using fixed options.
Lets readers tune a split keyboard's geometry to their wrists without buying a third-party tenting kit or accepting the stock angle.
Magic Pen uses an LSTM model trained on pen stroke data to automatically switch digital pen modes during document annotation, eliminating menu-based mode selection. Evaluated with 27, 18, and 8 participants across training, comparative, and deployment studies, with transfer learning for per-user tuning.
A concrete HCI study with measured user preference over menu-based pens, useful for anyone designing or selecting stylus annotation tools for tablet-based document work.
A study introducing Wistful, a research probe that captures 'creative reading traces' during open-ended scholarly exploration. Testing with 16 HCI researchers found that familiarity and personal interests shape reading paths, and that trace artifacts make browsing differences visible for reflection and comparison.
Maps how researchers actually browse before formal search, suggesting trace artifacts as a low-overhead way to surface and compare reading strategies across teams.
Presents DREAM, an LLM-powered voice assistant that monitors conversational sleep diaries and uses guided reflection—drawing on behavioral sleep medicine—to help users interpret their own sleep changes. A six-week field study (N=14) found greater personal insight, motivation, and clearer rationale for behavior change versus generic education.
Concrete field study of an LLM agent applying guided discovery rather than direct explanation, with co-design by sleep specialists and findings on user agency.
The paper proposes organizing thousands of autonomous research agents under explicit institutional structures, including competitive compute allocation through proposals, independent review, and a human governor with no task assignment. In a 10,000-agent simulation aimed at improving language model pretraining, one lab reportedly reached similar quality with about 30% less compute, a result other labs have not yet confirmed.
Proposes explicit institutional design for large agent populations instead of ad-hoc organization. Six principles plus a 10,000-agent run make it more than a manifesto, though the headline efficiency result is still contested.
Paper presenting MAScope, a two-stage framework that recovers communication topology from multi-agent LLM execution traces and uses it to classify coordination failures. Experiments show topology context roughly doubles Macro-F1 for a small model and cuts diagnosis cost to about 6% of a high-quality baseline.
First systematic method to extract communication topology from LLM agent traces and use it as conditioning for failure diagnosis, with concrete accuracy and cost numbers.
Researchers interviewed 14 users to study when AI companions should surface remembered information. They developed Reconsider, a single-call procedure with five checks and four handling modes, evaluated across 80 scenarios and five LLM models. LLM judges preferred it overall, though the margin did not hold for GPT or Claude.
A concrete memory-use framework with its own caveats: judge preferences did not replicate on two major model families. Useful reference for anyone designing companion products that retain user history.
Research paper proposing gaze-based activation for an embodied AR assistant in co-located settings, with visible listening status on the assistant's body to manage activation, continued interaction, and release. A 25-participant study (500 interaction outcomes) found gaze acquisition preceded speech in 98.8% of attempts, but revealed a release problem: users missed status changes when gaze returned to work.
Empirical study of a concrete interaction pattern for AR assistant address and turn management — relevant evidence for anyone designing or evaluating embodied AI assistants, with measured failure modes included.
EmoToon is a technology probe that lets non-professional artists create sketch-like comic storyboards guided by their own emotions, with iterative AI assistance. A controlled study with 25 participants found AI improved emotional expression, aesthetics, and exploration, but reduced creative ownership.
Quantifies the trade-off between AI-assisted output quality and the user's sense of creative ownership in a specific workflow — useful tension to weigh when designing co-creative tools.
Peer-reviewed study examining user roles, engagement, and perceptions when AI generates follow-up questions during semi-structured interviews, contributing empirical evidence on human-AI collaboration in qualitative research workflows.
Empirical HCI study on where AI fits in semi-structured interviewing; useful for researchers weighing AI-assisted follow-ups and role boundaries in fieldwork.
Paper formalizes a five-layer trust model for multi-agent LLM systems via three components: a cross-layer synergy operator, a no-regret online weight estimator grounded in observed failures, and Trust-Gated Capability Control that issues revocable grants only when composite trust clears thresholds. Includes provable bounds, closed-form fixed point, and a 20,000-draw numerical study with a sleeper adversary.
Formal treatment of the trust-vulnerability trade-off in multi-agent LLM systems with provable guarantees. Worth reading for designers of agent orchestration layers, though it remains theoretical rather than an implementable tool.
Paper identifies 'visual orchestration tax': in agentic VLM pipelines, the same static image is repeatedly reconstructed as image-conditioned requests across specialist agents, causing 66.8-75.6% touch redundancy. Proposes audit metrics (M1, M2) and SharedVisCache, a contract-aware reuse hook that preserves outputs while reducing physical-layer vision calls 4x.
Names a measurable redundancy mode in multi-agent VLM stacks and ships a contract-checked cache that cuts compute calls without changing outputs. Useful before scaling agent count.
A research paper simulating heterogeneous social networks built from multiple LLM base models reports that the engagement an agent receives depends more on its base model than on its assigned persona. The model-driven effects strengthen as more models are mixed in, and content analyses link the effect to lexical patterns predictive of engagement.
Counterintuitive empirical finding for anyone running multi-agent setups: model identity shapes network outcomes more than persona, and the effect compounds with model diversity.
A scalable gamified workshop for 226 engineering Master's students used a mobile web interface to practice prompt-writing for non-reasoning and reasoning LLMs on grid-based navigation tasks, culminating in a live Boston Dynamics Spot demonstration. 81.5% reported substantial learning; prompt analysis showed a shift from step-by-step to higher-level guidance strategies.
Documents a concrete, code-released workshop format with measured outcomes on how students adapt prompting strategies when working with reasoning versus non-reasoning LLMs.